Tag: Synapse Analytics (page 1 of 1)

Limitations of Azure Synapse Analytics SQL Pools

In the past couple of months, I have run into some annoying limitations and unsupported features with T-SQL in our Azure Synapse Dedicated SQL Pools, which is where my team puts our data warehouses for reporting needs across our business. These unsupported features were a bit surprising to me, which is why I’ve decided to share them in this post. This is certainly not going to be an all-inclusive list of things you can’t do in Dedicated SQL Pools that you can in a normal SQL database, but I will keep it updated as I run into more barriers in the future.

What’s in this post

No Primary Keys

When you understand that the Dedicated SQL Pools (DSP) are meant to be used as Online Analytics Processing (OLAP) data warehouses for analytics and reporting purposes, it makes more sense that primary keys are not allowed on tables since that would affect performance. I did not initially put that concept together until I was trying to create a new table on the DSP and got the following error:

Screenshot showing a T-SQL command to create a Primary Key on a table in SQL Server Management Studio and the corresponding error since the command is not supported on this type of database

The full error message is:

Enforced unique constraints are not supported. To create an unenforced unique constraint you must include the NOT ENFORCED syntax as part of your statement.

Unfortunately, there is no workaround for this limitation. You must accept that you will not be able to enforce uniqueness on your tables in the DSP, unless you want to have “uniqueness” in name only and not have it actually enforced.

No Foreign Keys

In the same vein as above, foreign keys are also not allowed in a Dedicated SQL Pool (DSP), since that would also hinder the performance of OLAP queries if they existed. When trying to create a foreign key on a table in a DSP, you get the following error:

Screenshot showing a T-SQL command to create a Foreign Key on a table in SQL Server Management Studio and the corresponding error since the command is not supported on this type of database

The full error text is:

Parse error at line: 3, column: 1: Incorrect syntax near 'FOREIGN'.

This error is different from the error received when trying to create a primary key, because this query simply returns a parsing error; the query processor doesn’t even understand the concept of trying to apply a foreign key constraint to the tables in this database, since it’s a DSP.

There is no workaround for this limitation beyond accepting that you will not be able to maintain relationships between tables in your database for this type of server.

No Default Constraint using a Function

This is the constraint I am most sad about not being able to apply to tables in a Dedicated SQL Pool (DSP), since I think it would be really useful for certain situations. But again, needing to apply a default value function for every row inserted into a DSP table would slow down the processing speed, which is bad for OLAP queries.

When you try to add a default constraint using a function or expression to a table in a DSP, you will get the following error:

Screenshot showing a T-SQL command to create a Default Constraint on a column in SQL Server Management Studio and the corresponding error since the command is not supported on this type of database

The full error message for that is:

An expression cannot be used with a default constraint. Specify only constants for a default constraint.

However, you are still allowed to add default constraints that have a constant value, like this:

ALTER TABLE dbo.CUSTOM_FORECAST_Raw
ADD CONSTRAINT DF_MyDefault
DEFAULT '1900-01-01 00:00:00' for UploadDatetime;
Screenshot showing a T-SQL command to create a default constraint with a constant value on a column in SQL Server Management Studio and the corresponding error since the command is not supported on this type of database

My most common use of a function in a default constraint for a column is to set an update datetime for the row, and that is precisely what I was trying to accomplish when I found this limitation. There is no direct workaround for this limitation. What I did to subvert it was to add the UpdateDatetime value to the column further upstream in the ETL process. Hopefully, that type of workaround will be doable for you as well.

No Multi-Line Inserts

This limitation is one I truly don’t understand, and I was really confused about it when I first ran into it during development. In a normal SQL Server database, you can insert multiple rows into a table at once using the syntax INSERT INTO dbo.MyTable VALUES (value1, value2...), (value3, value4...);. Running that command would insert two different rows into the table at the same time. That syntax is not allowed in Dedicated SQL Pools (DSP).

If you were to run the same command on a DSP, you would get this error:

Screenshot showing a T-SQL command to add multiple rows of data at once in SQL Server Management Studio and the corresponding error since this command format is not supported on this type of database

The exact error message for that scenario is:

Parse error at line: 2, column: 19: Incorrect syntax near ','.

This is another scenario where the query processor doesn’t even know how to approach this code, even though it would work just fine if I instead ran it on a normal SQL Server database.

The workaround for this limitation is to create an INSERT statement for every row of data you want to insert into your table, or use a pipeline in the Synapse workspace to load data instead.

INSERT INTO dbo.MyTable VALUES ('AR',5103);
INSERT INTO dbo.MyTable VALUES ('CA',6111);

I only needed to load a few test rows into a table on my DSP for testing purposes, so the multiple INSERT statements worked in a pinch. I would not want to do that if I were adding more than a few rows to the table.

Cannot use sp_rename

For this scenario, I’m not entirely sure what the reasoning is behind removing the ability to run this particular procedure (and likely others like it), but I have learned that in a Dedicated SQL Pool (DSP), you are not able to rename objects in the database using the system stored procedure sp_rename. Instead, you now either need to just not rename your object, drop it and recreate it, or use a new command called rename object, which has a different syntax.

When you try to run the sp_rename procedure on your DSP, you will get an error like this:

Screenshot showing T-SQL commands to rename tables using the sp_rename procedure in SQL Server Management Studio and the corresponding error since the command is not supported on this type of database

The full error message is:

"An insufficient number of arguments were supplied for the procedure or function sp_rename"

This is an odd message, because it leads you to believe you’ve typed something wrong instead of the fact that this procedure is not valid on this type of database. I’m not sure why the procedure is even installed on the database, given that it doesn’t work as it does on other databases.

When I first got that message, I wasted time going to the documentation and verifying that I did have the correct parameters for the procedure. The following message is displayed at the top of the documentation page, but that isn’t specific to any given T-SQL command that may not work, like the one being documented on the current page. Plus, the notice only warns for serverless SQL Pools and not dedicated SQL Pools, like what I am working with.

Screenshot of a note in a Microsoft document about the sp_rename procedure, saying that some T-SQL commands are not supported for Azure Synapse Analytics serverless SQL pools

Mostly, when it comes to this system procedure not working, I am annoyed that, from the documentation of the procedure, it seems like it should work in this scenario. That includes the existence of the green checkmark next to “Azure Synapse Analytics” at the top of the page!

Screenshot of the top of the Microsoft document for the sp_rename procedure showing the supported list of database types the page applies to, which includes Azure Synapse Analytics

How to Rename Tables on a Dedicated SQL Pool

If the main system stored procedure for renaming objects doesn’t work for DSPs, how then are we supposed to rename objects as needed? Or are we out of luck and have to drop and recreate the table, or leave its name alone? At first glance, it does seem like we may be out of luck, because even the “Rename” option in the right-click menu on a table is grayed out and won’t let us change it from there:

Screenshot of the right-click menu of a table in the Object Explorer of SQL Server Management Studio showing that the Rename option is disabled and grayed out.

There is a way to rename, it’s just a little harder to find! With this type of database, there is a new command rename object that will let you rename a table. The syntax for that looks like:

rename object MySchema.MyTable to NewTableName;

That command worked successfully for me in my scenario of renaming a table that I wanted to mark for future deletion, as shown by this screenshot:

Screenshot showing a T-SQL statement to rename a table using the "rename object" command in SQL Server Management Studio with no error messages since it is supported for this type of database

With further reading of the sp_rename procedure documentation, if you scroll all the way to the bottom part with Examples, there is another note that the sp_rename feature is currently only in “preview” for Azure Synapse Analytics and is therefore only available for objects in the dbo schema. And honestly, that’s a little silly to me. It’s also silly that you wouldn’t find out that information unless you looked for examples; the information was not up in the main section of the documentation, so it isn’t as easy to find.

Screenshot of the Microsoft document for the sp_rename procedure saying that the procedure is still in preview for Azure Synapse Analytics so is only supported for the dbo schema and no custom schemas

If you would like to read further on the new syntax for renaming tables in Dedicated SQL Pools, you can review the document for the rename object command.

Summary

SQL Pools in Azure Synapse Analytics give you a lot of great performance and features that are specifically tuned for use in Data Warehouse situations, but those performance improvements do come with a cost–not being able to do things exactly as you are used to with standard SQL Server databases. I’ve struggled quite a bit with database development on this style of database, since it seems like every time I want to do something on the database, I hit a temporary wall of differences that I didn’t expect. I have obviously found an explanation for or a workaround to most of these problems, as evidenced by the information above, but it’s not a welcome interruption to my workflow. I hope that you will hit fewer walls in your own database development now that you’ve read through this post.

Related Posts

Troubleshoot ALL Layers of Your Data Flows

This is going to be a short post, which I am writing as a reminder for my future self as well as any of you reading out there.

If you are troubleshooting an error with your pipeline, especially if you work in a database system that has layered views, make sure you fully dig down through all layers of your data setup before you make a ticket with Microsoft. I learned this the annoying way over a work week while working through a ticket with Microsoft for a very strange issue I was seeing in a pipeline that uses a Synapse Serverless SQL Pool. We had checked so many things that week with no luck in changing the outcome of how the pipeline runs, and then the pipeline just went back to working when I ran it outside of its schedule.

What’s in this post

The Error

The error I was seeing made it look like the Serverless SQL Pool views, which use an OPENROWSET call to a parquet file, were referencing the wrong source file even though I confirmed multiple times that the view definitions were correct. For example, the view was written to use parquet files under TestDatabase/MyTable/** as the source files, but the error was making it seem like they were instead pulling data from TestDatabase/OtherRandomTable/** which was confusing to say the least. I thought that the Serverless node was broken or had a bug that was making the views look at “OtherRandomTable” files instead of the correct files.
The Cause

The error happened because multiple views used a CROSS APPLY to another view tied to a parquet file in a data lake, and that parquet file was being deleted and recreated by a parallel pipeline. When the failing pipeline tried to reference its views, it couldn’t find that base view because the source file had not yet been recreated by the parallel pipeline. Makes sense and is so obvious in hindsight, but it took Microsoft support directly asking me to make me realize that I had a view referencing another view, which I needed to check the definition of.

The change I needed to make was to update the pipeline triggers so that the process deleting and recreating the base view would be done making the parquet files when the second pipeline ran and tried to use those files.

If I had done my due diligence and dug through every layer of the data environment, which I am normally good at with other scenarios, I would have quickly and easily discovered the issue myself. But sometimes we need to learn the hard way because our brains aren’t running at full capacity. (It also helps that I finally had dedicated time to set aside to this problem and so wasn’t trying to multitask multiple work items at once.)

Summary

If you are troubleshooting ETL failures of any kind, make sure you dig down through all layers of the process to ensure you have checked everything possible related to your failure before reaching out to support. They’ll happily help you find what you missed, but it will save everyone time if you can figure it out yourself first.
Related Posts

Synapse Serverless SQL Pool View Seemingly Caching Data

This morning I ran into the strangest data issue I’ve seen with Azure Synapse Serverless SQL Pools, which is that a view we have seemed to be caching data, and that data was very weird, wrong for the column data type, and causing issues with an application query. While I still have no idea how or why this happened since the serverless SQL pools aren’t supposed to cache data like the standard SQL pools, but I thought I would share what I saw to maybe help others (and to see if anyone else knew why this was happening).

I was able to correct the issue to get the app query working again, I just won’t ever know why (unless you know why, in which case you should share in the comments below!).

What’s in this post

Background

I first learned of this issue through an application developer on another team emailing me saying that they were running the same query on our serverless and dedicate SQL pools on Synapse, and the query was working as it normally does on the dedicated pool but was giving the following error on the serverless SQL pool:

Msg 241, Level 16, State 1, Line 3

Conversion failed when converting date and/or time from character string.

The query they were trying to run is one that hasn’t had any issues in the past.

In our setup, we load the same data into both our serverless and dedicated SQL pools for different use cases, and both are loaded from the same set of delta parquet files in a Data Lake on an Azure Storage Account. Which means that there should be no reason that the query running on one should run and the other not.

The first step of my troubleshooting process was to replicate the error that the developer sent me, and I was able to do that. I then reviewed the very long query for anything that was doing a CAST or CONVERT on a date field, which helped me narrow down the problem to a single view on our serverless pool.

The Weird Data

After I identified the one view that seemed to have the bad data on a date column, I ran a DISTINCT query on that one column and received the most confusing results.

Screenshot of SQL query in SSMS demonstrating the bad data contained in the date column of my serverless SQL pool view.

None of those values look like dates to me. Which made me question myself and the data type for that column “order_entry_dt”, since a data column couldn’t possibly hold string values like this. But no, the column data type does say it’s a “datetime2”.

Screenshot of the problematic view column and its data type

At that point, I started downloading and reviewing individual parquet files from the Data Lake to see if any of them had that weird data, and none did.

The next step I took was to look at the view definition to see what it was doing again, to make sure I was looking at the correct source data, and that all looked good. I decided that I would run my distinct query on the view itself, but then also run the exact same query using the SELECT statement that defines the view, to see what both returned. And that made things even more weird, because it confirmed that the source data should be correct, but the view is somehow wrong.

Screenshot of two SQL queries in SS<S showing that selecting from my view and running the select contained in the view definition return different results

If the view definition uses that exact same “OPENROWSET” query as it’s definition, why does the view return different data than the “OPENROWSET” query??

Correcting the Problem

Even if I couldn’t figure out why or how the problem data happened, I still needed to figure out how to resolve the issue so that the app query would start working again. What I decided to do was drop and recreate the view, which is easy given how simple the view definition is.

Once I dropped and recreated the view, I ran the exact same queries as above again, yet this time the view started to return data that I expected.

Screenshot of two SQL queries in SSMS showing correct data being returned from selecting from my view and run the query that is the view definition

So why was the view data weird?

While writing this post, I decided that I couldn’t let this go without knowing why the data got weird, so I decided to test out some theories for myself. (Spoiler: I couldn’t figure it out.)

My first theory was that someone ran an UPDATE query on the view accidentally to change the data. But that is not allowed in serverless SQL Pools, which I even tested out myself. By making a copy of the problem view with a different name and then trying to run an update statement, I was able to prove to myself that this theory was not how the bad data was created.

Screenshot of a SQL query in SSMS where I attempted to update data in a column in the view, which pulls data from a parquet file so thus cannot be updated

Then I thought maybe someone wrote a query to change the underlying parquet files directly, but that doesn’t seem to be possible either.

The only thing I can now think of is that someone accidentally overwrote the source parquet file, or made a second that was also used as source data, which contained the bad data. Parquet files are immutable, so there should have been no way for someone to update a parquet source file with bad data to get bad data into our serverless pool view.

I have learned many things today, but one of those things is not why this issue happened, unfortunately.

But like I said above, if you have ideas, I would love to hear them in the comments below!

Summary

If you run into this same strange issue where a Synapse Serverless SQL Pool view has weird data that you don’t expect, and that data doesn’t match the query that is used as the view data source, drop and recreate the view to fix the problem.

Related Posts

Azure Synapse Hive Connector V2.0 Issues

If you use a Hive Linked Service in your Azure Synapse workspace, you have probably been getting a banner at the top of your workspace every time you sign in telling you that you have linked services that are about to be deprecated so you should update them. If, like me, you go ahead and do that upgrade from version 1.0 to version 2.0, which is touted as being as simple as toggling a switch, you may have been disappointed to find that you now have an error with your connector that prevents your pipelines from running. If this is relatable to you, keep reading because I will tell you how you can resolve the issue.

Fortunately or unfortunately, depending on how you look at it, I was a preview tester for Microsoft for the fix to the Hive V2.0 connector issue because the problem had already been reported and had a fix in progress when I created a ticket with Microsoft support. The solution has now been released and is available for you to implement if you need it.

What’s in this Post

The Problem with the Hive 2.0 Connector

For a couple months, my team was being annoyed with a banner every time we opened one of our workspaces which utilizes a Hive linked service, telling us that we have a linked service version that is going to be deprecated soon. In August, I finally decided I had enough of the banner and decided to do the requested upgrade to our Hive Linked Service, to upgrade to version 2.0. Making the change was simple enough, changing the radio button we had selected in the settings of the linked service (LS), and I didn’t even have to fix any settings of the LS after making the switch like I had to do with an upgrade to our Oracle connectors. All previously saved settings stayed where they were, so I saved the change and merged it.

A couple days later, on the next run of our pipeline that uses that linked service, we got the following error on the “Copy Data” activity which pulls data from the Hive data source into our data lake.

"ErrorCode=FailedToConnectMSDISource,'Type=Microsoft.DataTransfer.Common.Shared.HybridDeliveryException,Message=Failed to connect to the connector. Error code: 'AuthenticationError', message: 'One or more errors occurred., ErrorCode: AuthenticationError',Source=Microsoft.DataTransfer.Connectors.MSDIBridgeAdapter,''Type=Microsoft.DI.Driver.Hive.Exceptions.HiveConnectorException,Message=One or more errors occurred., ErrorCode: AuthenticationError,Source=Microsoft.DI.Driver.Hive,''Type=Apache.Arrow.Adbc.Drivers.Apache.Hive2.HiveServer2Exception,Message=An unexpected error occurred while opening the session. 'Required field 'client_protocol' was not present! Struct: TOpenSessionReq(client_protocol:null)',Source=Apache.Arrow.Adbc.Drivers.Apache,''Type=Thrift.TApplicationException,Message=Required field 'client_protocol' was not present! Struct: TOpenSessionReq(client_protocol:null),Source=Apache.Arrow.Adbc.Drivers.Apache,'",

The important part of that error message is An unexpected error occurred while opening the session. 'Required field 'client_protocol' was not present!.

As any developer then does, I started googling that error but didn’t find any pages with that same error for Azure Synapse related Hive issues. But I did find several similar errors with different uses of Hive that were caused by version issues between the client and the server, essentially the client got upgraded beyond what the server version was, which caused a similar error for others.

For my pipeline, I do not control the Hive data source that we were failing to pull from because that is managed by one of my company’s customers. I tried to get information about their Hive version to see if it was something they could fix, but I quickly hit a dead end and they told me to make a support ticket with Microsoft. Which I did.

Thankfully Microsoft was immediately helpful and I got to work with a very kind and knowledgeable support woman, who immediately tracked down and found that the issue I was having was one that the engineering team was already working on resolving. Great! There was a fix already in the works! And a couple days after being told I just needed to wait for the fix to be sent out, I received a message from the support agent asking if I would test out their proposed fix to the problem, which was an updated version of the Self-Hosted Integration Runtime (SHIR) that allowed us to connect our systems to our customer’s.

How to Resolve the Problem

The Self-Hosted Integration Runtime (SHIR) that Microsoft wanted me to test was easy to install on our server where we normally run our SHIR for the workspace I was upgrading. They provided a download link to me, so I hit that then easily install the SHIR like you normally would and it upgraded in place. The version of the SHIR I tested for them was “IntegrationRuntime_5.58.9364.4”.

Once I installed that on our server, I updated the Hive connector again (since I was forced to downgrade while the solution was being developed so I could continue getting our data) and this time, the test connection worked. I then committed the change and ran my pipeline, and it successfully completed the “Copy Data” activity that had been previously failing with the 2.0 version of the connector.

The only problem we have now is that the 2.0 version of the connector seems to have changed how data types are handled for Parquet files in Data Lakes, so now I need to remap data types between our Data Lake and the final data warehouse to get the pipeline completely working again. I had to remove the test SHIR from our production system at that point anyway since they told me we couldn’t use it in production yet, so when I do the official upgrade to the 2.0 Hive connector, I will also need to make that data mapping fix.

As of writing this post, the SHIR that I believe contains the fix is live on the site where you normally download that software, except the version is slightly higher. What’s available on their download site is “IntegrationRuntime_5.58.9377.1”. If you are having the same issue I am with this connector upgrade, give this latest SHIR a try to see if that resolves your issue like the test version did for mine. I will update this post once I have done my final upgrade and have confirmed that the SHIR version available online fixes my problem for good.

Screenshot of the Microsoft webpage listing the available Integration Runtime downloads

Summary

If you started to experience connection failures on your Hive linked service in Synapse after changing the version of the linked service from V1.0 to V2.0, update your Integration Runtime to version 5.58 or later to get the problem fixed. When updating the linked service, there is no mention of needing to upgrade the SHIR unless it is really out of date (when I first tried upgrading the connector I couldn’t because we were on SHIR 5.52), so you will need to be aware of this mismatch yourself.

Let me know down in the comments if you also ran into this issue with the upgrade!

Related Posts

TechCon365 Day 2 Recap

Today at TechCon365 in Atlanta, I did another full day session of the pre-con, this time covering everything in the realm of Microsoft Fabric. Before today, I knew hardly anything about Fabric, aside from it being something that Microsoft was pushing our team to use for a new project I wasn’t involved with. The workshop, which didn’t have any hands-on work but was still good, was led by John White and Jason Himmelstein. The two speakers did an excellent job at teaching all aspects of Fabric without being boring. This was the introduction to Fabric as a concept that I’ve been needing for months.

Note: The content below is not guaranteed to be accurate, it’s just what I took away from the workshop. In the coming months, I will be learning more about these tools myself to fact check everything and see if the new tools will work for my team.

What’s in this post

Goodbye Synapse

For me, the biggest takeaway of things I learned during today’s workshop is that Microsoft intends to get their customers migrated off Synapse as the data movement platform and into Fabric and its OneLake. As of now, Synapse as a product no longer has a product manager (according to the presenters), which means that Microsoft does not intend to make any feature updates to that tool. There is still a maintenance team for the product to fix any issues that may arise and to keep it running, but there are no long term plans for it anymore.

Synapse going away is concerning to me because my company only recently migrated to Synapse off of SSIS. My fear is that if we spend a ton of time and energy converting our ETL systems into Fabric, that as soon as we get the work done, we’ll need to start anew with whatever product line Microsoft releases next, just like what we just did with SSIS to Synapse. I understand that cycles like this are everyday occurrences in the technology sector, but I also know that my boss and the executives at my company are likely not going to be happy when I tell them what I learned in today’s workshop.

If you’re in the same situation my team is in, you are totally in Synapse and maybe just wrapped up getting there so are wary to move on to the next transition to Fabric, don’t worry too much. The presenters did assure us that Synapse will be supported for a while yet, no concrete plans have been announced to retire it. Based on that, John and Jason recommended that teams stop doing any new development using Synapse and instead start to do new development in Fabric to work as real-world test cases of how useful it can be. I haven’t yet done anything like that, so the usefulness is still unknown to me personally.

Hello Fabric

Fabric is being sold as the one stop shop for all things data in the Microsoft universe, the future of all data analytics and processing. No longer is Fabric going to be Power BI 2.0; now it will serve as the location for anything you need to do with data. While the sales pitches are great, I am wary of the transition, like I said above already. I dislike when companies claim that their new tool is going to solve all your problems, because nothing is ever that great in reality. But here is what I learned today.

OneLake: Put every speck of data here

With each tenant, Microsoft gives you a single OneLake, because it should be your one data lake for your organization, just like there is only a single OneDrive for each user. No more having dozens of storage accounts to act as separate data lakes for different processes. Now you get the one and you will like it. More details I learned:

  • Parquet files: the reigning champions
  • A “Shortcut” to the source data
    • If you want to get data from a source system, like your Oracle finance database for PeopleSoft finance, you can add a “Shortcut” to the data source without having to pull the data into OneLake with a normal ETL process.
    • This concept is the most intriguing to me, and I really want to see how it plays in real life with real data and systems. Could be too good to be true.
  • Security redefined
    • They’ve developed a new way to manage security for the data that is supposed to reduce overhead. They want to have you manage security in only one place, just like you’ll be managing all your data in one place with OneLake.
    • This feature is still in preview, so remains to be seen if it works as well as Microsoft claims
  • File Explorer: An old but good way to explore your data
    • A new plugin for Windows has been created that will allow you to view your OneLake data through the Windows File Explorer, like they’re normal files. Which they are, if they’re Delta-Parquet flat files. The new feature is OneLake File Explorer.
    • You can also view your OneLake data files through Azure Storage Explorer, which is a good second option as well since my team already uses that for other purposes.

For the OneLake concept, I like that it is trying to prioritize reusing what you already have–tools, data, reporting frameworks–so that you don’t have to keep reinventing the wheel for each new data flow process you need to create. The concepts are good, so I’m eager to use them for myself after the conference.

Lakehouse

This is a new way to store data that is offered exclusively by OneLake in the Microsoft ecosystem. It combines the concepts of data lakes and data warehouses by using Delta Parquet format files. It gives you the ability for ACID compliant transactions on the data files while also still having compressed and cheap data storage like a data lake.

Data Factory

This is the part of Fabric that is replacing Synapse pipelines. In the demos during the workshop, I could see that the Dataflow Gen 2s and the data pipelines look almost exactly like what is currently available in Synapse, which is promising, because then at least I don’t need to learn a new GUI. Like with Synapse, the Dataflows are still backed by Spark engine to allow for parallel processing and high throughput. Both tools allow you to move data from point A to point B (the OneLake) for the scenarios where Shortcuts won’t work and you still need to literally move data between systems.

Fabric Native Databases

If the other new data storage types in OneLake and Fabric weren’t enough for you, there is now also going to be Fabric-native databases available for use. These will be SQL Databases (and some other database types) that you create directly in Fabric instead of creating them independently then joining them to the OneLake with a Shortcut. This change to Fabric is what they are intending to use to take Fabric from a data analytics platform to a full data platform. However, the presenters of today’s workshop did caution that they don’t recommend putting your production systems into these native databases yet, since they’re still new and not well-tested in the real world. But maybe in the near future, we truly will be doing 100% of our data integration engineering in Fabric.

Summary

With this technology, it feels like we could be at the cusp of a new big wave of change for how we operate in the data realm, so I am really interested to see how things play out in the next year or two. Using Fabric for all things data could be the next big thing like Microsoft is trying to sell, or maybe it will simply fade into being just another option in the existing sea of options for data manipulation and analytics in the Microsoft ecosystem.

Do you think Fabric is going to be the the next big thing in data technology like Microsoft claims?

Related Posts

How to use Logic App to send email from Synapse Pipeline

A task that I completed a while ago that I wanted to share was creating two different pipelines for a business user to load data to and from one of their databases to another server for monthly processing. The business user requested that they receive an email if the pipeline failed so that they would know sooner rather than later that there had been a problem with processing. Unfortunately, there isn’t currently a way to natively send an email from a Synapse Analytics pipeline, there isn’t a built-in activity for that (that I’m aware of). To enable the functionality requested by the business users, I had to create a custom system to send an email.

What’s in this post

Overview of the process

Since there isn’t a native activity within Synapse Analytics that allows you to send an email, the workaround system I created is to make a Logic App that will send an email when triggered by an HTTP request, then add an HTTP activity in the pipeline to trigger the pipeline and feed through error information to the Logic App to generate a useful email. Keep reading to learn the details of how to setup such a process.

Creating a Logic App to Send an Email

1. Click on the component “Add a trigger” in the designer. In the search box, type “request” and then select the option that says “When an HTTP Request is received”.

    2. Click on the link to “Use sample payload to generate schema”

    3. Enter a simple JSON-formatted string containing the values you will need to use to send the email

    4. Click “Done” when you’ve included all the parameters you want to include in your incoming JSON values, and your simple JSON will be automatically formatted in the exact way needed for the payload to handle the request.

    5. Choose the METHOD that will be used for the HTTP request, select “POST”

    6. Click into the open area of the designer to close the editor for the HTTP request component then click the “+” under the component to add another to the flow

    7. In the search box, search for “outlook”, scroll down until you see the section for “Office 365 Outlook” and click the component for “Send an Email (v2)”

    8. If you haven’t logged into an email account through the Logic App yet, it will request that you do so in order to start specifying how the email should be sent. Go through the process of signing into an email account. I recommend using a service account email instead of your own email, unless you’re the only person that will ever be working on this process in the future.

    9. Click into the “To” box in the properties of the “Send an Email” component, and you’ll see two blue icons pop up to the left of the box that will allow you to dynamically enter information into that text box. Click the top icon that looks like a lightning bolt to pick values from the previous step of the process.

    10. In the box that opens, select the “to” value from the HTTP request component to fill into the “To” box of the email properties.

    11. Repeat the same steps for the Subject of the email and the Body of the email.

    Adding the Email Capability to your Synapse Pipeline

    After saving the Logic App, you will be ready to use it from your Synapse pipeline. Once saved for the first time, you will now see that a URL has been generated for the HTTP Request activity which you will use to call the Logic App from your pipeline. Copy that URL.

    Return to your Synapse pipeline so that we can set it up to call the Logic App to send an email. Since we essentially created an API which we can hit to send an email, we need to add a “Web” component to our pipeline. In my case, I want to send an email to a business user when the pipeline fails since they are the key party interested in the pipeline failing. For that, I have added my “Web” component as the “On Failure” route of my pipeline (red “x”/line).

    Open the “Web” activity to set it up to hit your new API. Give the Activity whatever name you would like, in my case it is named “Send Failure Email 1”. Then go to the “Settings” tab and paste the URL into the URL field. Then for “Method”, choose “POST” since we want to send information to the URL from our pipeline.

    Next, we need to write the body of text to send to the API. This Body will need to match the formatting that we specified in the Logic App when we configured the JSON Payload. In that payload, I specified the following parameters should be required: To, Subject, and EmailBody. Based on that, I have written my Body for the Web activity as the following:

    {
        "to":"@{pipeline().parameters.EmailRecipient}",
        "subject":"@{pipeline().parameters.EmailSubject}",
        "emailbody":"Pipeline failed when trying to copy data for table @{item().TableName}."
    }

    When working with the expression builder in Synapse, you need to be very particular about formatting when using pipeline parameters or variables in an expression. Pay close attention to the double-quotes, the curly brackets, and the @ symbols. In my HTTP Body, I set the values of two of the parameters I send to the Logic App through pipeline parameters so that I only had to change them in one place and not in every iteration of the email component in my pipeline. If you don’t want to use parameters like that, you could hard-code the values of the key-value pairs in the body to whatever you would like, similar to how I set the value of emailbody.

    Click “OK” to close the expression builder panel. The very last thing we need to add to our “Web” activity is the Headers of the POST HTTP message, we only need to add one. Click the “+ New” button to add one, then enter the Name as “Content-Type” and the Value as “application/json”.

    Testing the Pipeline Email Capability

    Once you have finalized the addition of the “Web” activity in your pipeline, you are ready to Debug and test the changes, which you can do in the manner in which you normally test your Synapse pipelines. For me, I knew my pipeline was setup successfully in the way I wanted when I created a false failure scenario (since the email only sends when a component fails), I ran a debug, the previous component failed and I received an email containing the failure information that I wanted. Your testing may look slightly different.

    Summary

    Although Synapse Analytics doesn’t have a built-in feature for sending an email from a pipeline, you are able to build that functionality yourself fairly easily using a Logic App and a Web activity in your pipeline. I would love to hear if you found this method useful or implemented it yourself. Thanks for reading!

    Resources

    https://omnidata.com/how-to-setup-notifications-within-synapse-pipelines-using-logic-apps/

    Related Posts

    Reseeding Table Identity from Synapse Pipeline

    A task I was requested to implement a while ago in an Azure Synapse pipeline was to have the pipeline reseed a table identity column to prepare it for new data that will be calculated and inserted into the table as part of an optimizer solution someone is writing. This request challenged me to learn about identity reseeding since I had never even considered that would be something I would ever need to do, and it also challenged me to make that reseeding query work in a Synapse pipeline.

    The process isn’t difficult, but it was a little finicky since a higher level of permissions is needed to run the reseeding command, and some people, like me, might not want to give their Synapse pipeline sysadmin permissions. This post will cover general information about what it means to reseed an identity column and then how you can do that reseeding from a pipeline.

    What’s in this post

    Background

    I completed a project where we upgraded the database servers for a business group, putting their main database onto an Azure Platform as a Service (PaaS) database instead of an old Azure virtual machine. Part of the project was to see if we could rewrite their optimizer into a new Python script instead of their current, very dated, C-based program that requires a VM to run on. Unfortunately, the business group decided to not go with my new script (as I mentioned in a previous post), so we had to come up with a way for them to continue running their current DLL program in the updated environment. For those who don’t know, the PaaS Azure databases no longer have the ability to run DLLs natively like on-prem or Infrastructure as a Service (IaaS) instances do, which meant that we had to find a way to continue running their program without the ability to run it natively on their upgraded database server.

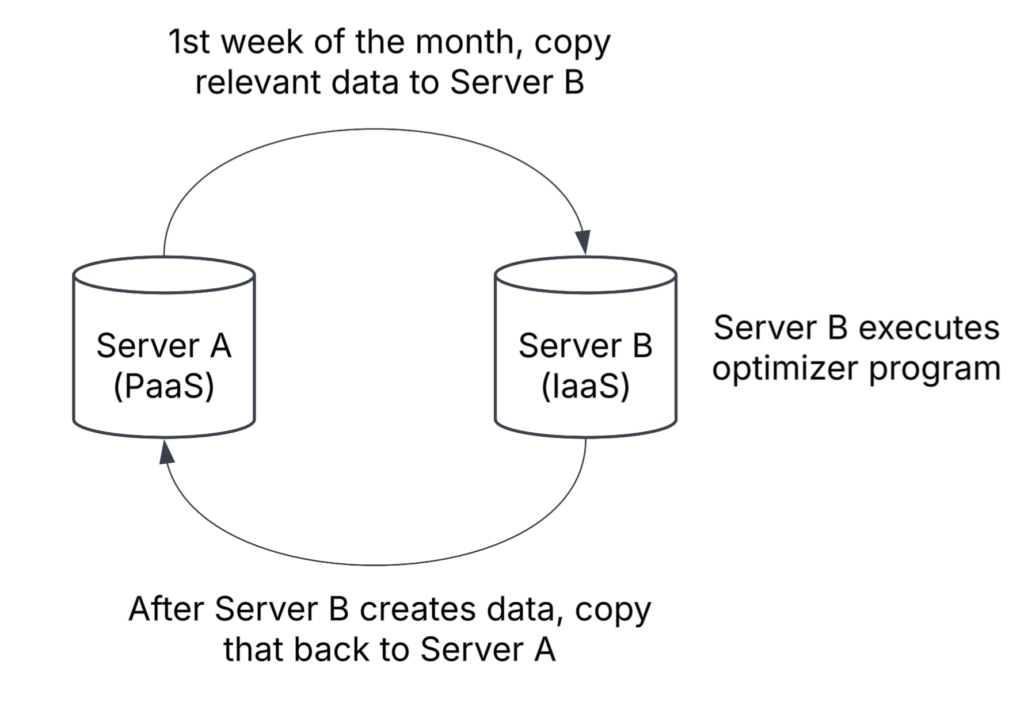
    The solution we came up with is to create a new and updated Azure IaaS VM that can run SQL Server and the DLL optimizer program. To get that to work and be cost-effective, when the time comes each month for their program to run, we are going to copy the relevant data for the optimizer from the main PaaS database into this VM’s database, the DLL will be executed which will calculate and load data into a couple of tables, then we will copy that calculated data back to the main server and power down the VM for the rest of the month.

    So what does that have to do with identity columns?

    Flow diagram that gives an overview of the process requiring me to reseed an identity every month

    One of the tables that will have its data generated by the DLL, which will then be copied back to the main table on the main server, has an identity column. On Server A, the table contains customer data up to the beginning of the current month and the maximum identity column value is something like 165487998. On Server B, where the new data for this month will be calculated and prepared to be loaded back to Server A, the table also has that same identity column but the table is truncated each month before calculating the new data. That means that if we did nothing about the seed value for the table on Server B, the identity column value would restart at 1 and work its way up as new data was loaded, which would cause primary key conflicts when the data is loaded back to Server A. We need to prevent that issue and start the current month’s records at the identity value where we left off on Server A, so I needed to find a way to update the identity seed value for Server B’s table when the pipeline runs each month.

    What is an identity column?

    An Identity Column is a column in a SQL Server database table that has its value automatically generated when a new record is inserted into the table. These columns are frequently used for primary keys (PKs) because an Identity Column must be unique, which is perfect for PKs. When you create an identity column on a table, the default is to have the value of that column start at 1 and increment by 1 every time a new record is inserted. Those default values can be changed to fit your needs. The value that you want the column to start at is called the “seed”; the value you want to increment the column by is called the “Increment”.

    For example, if I want to have a column that is automatically generated for me but I only want to have those values be even numbers, you can set the Seed for the column to be 2 and the Increment for the column to be 2, so the first value will be 2, the second will be 4, the third will be 6, and so on. But traditionally, I’ve only ever seen an Increment of 1 used, and I’ve never needed to set a different Seed value before this project.

    How do I know if a column is an Identity?

    Viewing the Column Properties

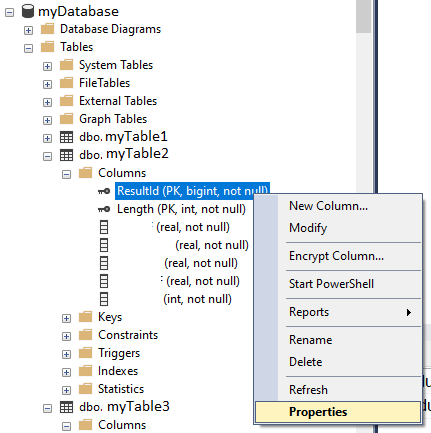
    There are several ways to find out if a column is an Identity, but the method I use is to look at the properties of the column using the Object Explorer, whenever possible. In the Object Explorer for your server connection, navigate to the table you want to check for an Identity, expand the table, then expand “Columns”. Once you have the list of columns opened, you can right-click on any column and select “Properties” which is where you’ll find if it’s an identity or not.

    Note: This method will not work with Azure PaaS servers, which severely limit the the information you can see from context menus and dialog windows.

    Screenshot of SSMS showing how you can access the Properties menu of a column to see if it’s an identity or not
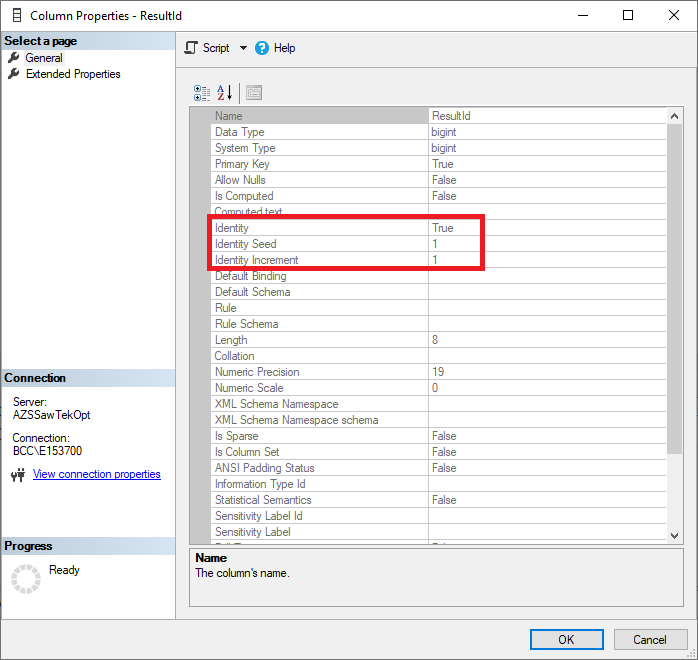
    Screenshot of the Properties window of a column showing that the column is an identity

    In the above screenshot showing the properties for my selected column, you can see that the value for the property “Identity” is set to “True” indicating that the column is an identity column. Then below that, you can see that the “Identity Seed” is set to 1 and the “Identity Increment” is also set to 1. Those two values mean that the first value that will be assigned to a row inserted into the table will be 1, then the value will go up by 1 for every new record inserted.

    Scripting the Table

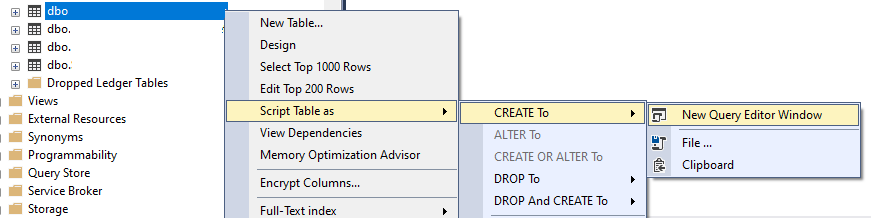
    Another way you could quickly learn if a table has an Identity column and what the settings for that column is would be to right-click on the table in the Object Explorer and script the table to a new query window.

    Script out the table you want to check for an identity column

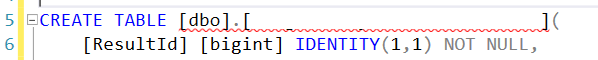
    Once the script has been generated, you will easily be able to tell if a column is an identity because it will be included in the SQL query to generate the table.

    Note: The values for Identity Seed and Identity Increment may not be accurate! In the screenshots above where I show how to find out if a column is an identity or not, both the Seed and Increment values show as being set to 1, but I know for sure that the Seed has been changed to a much larger value. The properties of the column may not reflect the actual values.

    Finding identity columns on Azure SQL Databases

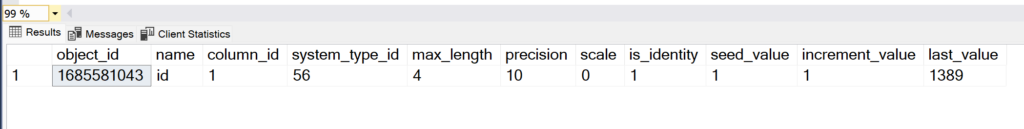
    As I said in a note above, you cannot simply right-click on a column in the Object Explorer for an Azure SQL Database (PaaS database) and view the properties for the column like you can with IaaS or on-prem versions of SQL Server. To see whether a table has an identity column on Azure SQL Databases, you will either need to script out the table like the previous section said or you can use the following T-SQL query.

    SELECT [object_id], 
    	[name], 
    	column_id, 
    	system_type_id, 
    	max_length, 
    	[precision], 
    	scale, 
    	is_identity, 
    	seed_value, 
    	increment_value, 
    	last_value
    FROM sys.identity_columns
    WHERE OBJECT_NAME(object_id) = 'TableName';
    Data you can find about a table’s identity column by using the identity_columns view

    When you run that query, you will see results like the following, which show the column that is an identity for the table. If the table doesn’t have an identity column, no results will be returned by the query.

    Checking Identity Properties with DBCC CHECKIDENT

    As I mentioned in a Note above, you can’t always trust that the values for Identity Seed and Identity Increment are correct in the Properties dialog or how they’re scripted out when you script out a table. So how do you know what the true values are? You can use the query on sys.identity_columns above or you can use the DBCC CHECKIDENT command.

    DBCC CHECKIDENT ('dbo.TableName', NORESEED)

    Note: Be very careful with the formatting of that `DBCC CHECKIDENT` command, because changing the `NORESEED` value to anything else and running it could reset or change the seed value inadvertently. Use caution when using this command and make sure you have it set exactly as you want. See the resources section at the end of this post for more documentation about this command to familiarize yourself with it.

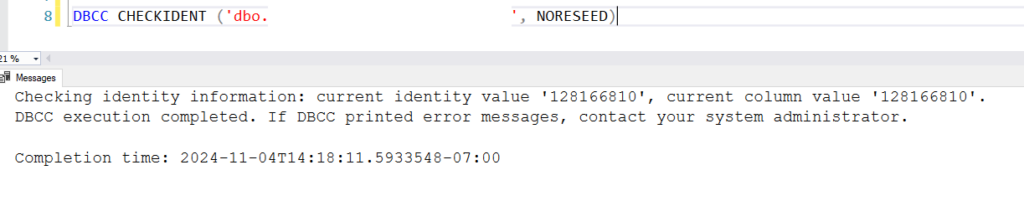
    When you run that above command, it will output a message that tells you what the Identity Seed value is currently set to and what the highest value of the column is as well (for when the Identity value has been incremented above the Seed value). In my example, I have only added a single record to my table so that one record has the outputted identity value, and the current column value is the same as the seed since there’s only one record in the table.

    The output of the CHECKIDENT function when you specify the NORESEED option

    What is reseeding?

    Reseeding is changing the value of the Identity Seed value for the Identity column so that it starts the value of the column at a number other than 1 or whatever it was originally set to. For my case, I need to retrieve the maximum value of the Identity column from Server A’s copy of the table, then set the Seed for Server B’s table to that value + 1 (so it starts at the next value above the current identity value in the source table). That means that I need to change the Seed value for my table on Server B to 128166810 instead of 1.

    How to manually reseed a column

    If you want to manually reseed an Identity column using a SQL command directly on the database, you can do so by using the following command:

    DBCC CHECKIDENT ('dbo.TableName', RESEED, <NewSeedValue>);

    You can use variables with this command as well:

    DECLARE @MaxIdentity int = 128166809;
    DECLARE @ReseedValue int = @maxIdentity + 1
    
    DBCC CHECKIDENT ('dbo.LengthAnalysisResultsHeader', RESEED, @ReseedValue);

    Permissions Needed to Run Reseed Query

    According to the Microsoft documentation (linked in the Resources section at the bottom of this post), one of the following permissions needs to be assigned to the entity that is running the DBCC CHECKIDENT command:

    • sysadmin server role
    • db_owner database role
    • db_ddladmin database role

    But that document also specifically mentions that Azure Synapse requires db_owner.

    How to reseed an identity column from an Azure Synapse pipeline

    For my scenario, I don’t want to run the reseed command manually because the Seed value will be changing every month when our processing runs and generates new data. I have added the DBCC CHECKIDENT command to my Synapse pipeline that’s already loading the data between my two servers so that it’s reseeded automatically right when it needs to be.

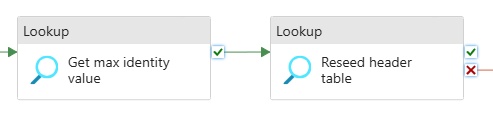
    In a Synapse pipeline, the reseeding based on a value from another server can be completed with two Lookup activities:

    You only need two Lookup activities in your synapse pipeline to programmatically reseed an identity column

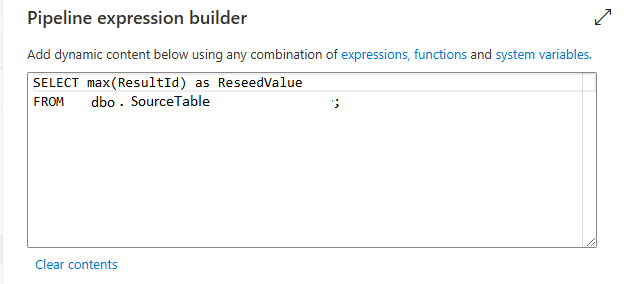
    First Lookup Activity – Get the Identity value

    The first Lookup will query the source database, in my scenario Server A, to get the maximum value for the column that is the Identity.

    Second Lookup Activity – Set the Identity value

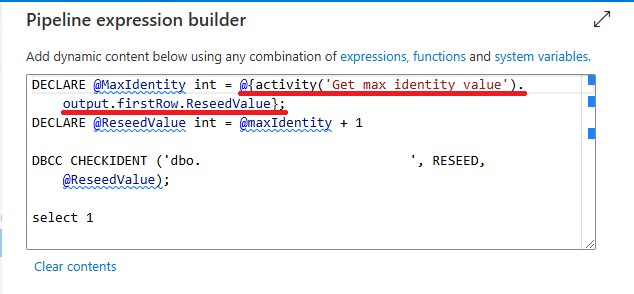
    The second Lookup will run the DBCC CHECKIDENT command, which doesn’t return any results, and will then run a SELECT 1; to satisfy the requirements of the Lookup activity that something should be returned:

    DECLARE @MaxIdentity int = @{activity('Get max identity value').output.firstRow.ReseedValue};
    DECLARE @ReseedValue int = @maxIdentity + 1
    DBCC CHECKIDENT ('dbo.TableName',RESEED,@ReseedValue);
    select 1;

    Let’s break that reseed query down a little more. The first line is creating a SQL variable called “MaxIdentity” which is an integer, and then setting the value of that variable to the output from the previous Lookup activity, which was called “Get max identity value”. To get the specific value from that preceding activity, we need to add .output after the activity call, then .firstRow to specify we want to get the value from the first row of the output of that activity, then finally add .ReseedValue which is the column name returned from the previous lookup activity.

    DECLARE @MaxIdentity int = @{activity('Get max identity value').output.firstRow.ReseedValue};

    Summary

    Reseeding the Identity column of a SQL Server table manually is a piece of cake because it only requires one small SQL statement. But to do the same process in an automated and repeatable manner is a different story. It’s not overly complicated to create a Synapse pipeline that reseeds a table’s Identity column on demand, but there are some quirks to getting the expressions to do so correctly which involved a lot of guessing and checking for me. I am still new to working with Synapse pipelines in-depth though, so perhaps this wouldn’t be such a difficult task for you more experienced Synapse developers. 🙂

    If you run into any issues while setting up the above process yourself, I would love to help as much as I can, so please leave a comment below!

    Resources

    Related Posts

    How to View Pipelines Associated with A Synapse Data Source

    This morning I received a question from a colleague about how to set up a new linked service for an on-prem server to use that as a data source for a pipeline. As part of my review of our current pipelines setup to make sure I was answering properly, I needed to find an example pipeline where we were already doing that. I had a linked service and associated data source doing exactly what I needed to share with this other person, but then I got to wondering if that data source was even used anywhere and set out to find out. As per usual though, Google betrayed me and wasn’t giving me anything related to the question I was asking, so I had to figure out the answer for myself. Which is why I am now sharing with you the simple way you can see what pipelines are using which data sources, and thus linked services, in your Synapse Analytics workspace.

    What’s in this post

    Seeing the Data Sources associated with a Linked Service

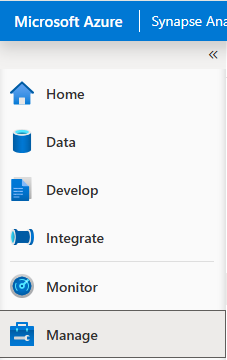
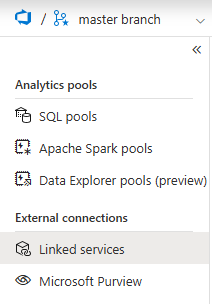
    In Azure Synapse Analytics studio, it is very easy to figure out what data sources have been created using a given Linked Service. To view this information, you go to the “Manage” page in the workspace, then select the page for “Linked Services”.

    Screenshot showing the left hand menu in the Synapse Analytics studio
    Open the Manage page to view Linked Services
    Screenshot showing the "Manage" menu with Synapse Analytics studio
    Open the Linked Services page under Manage to view all Linked Services in the workspace

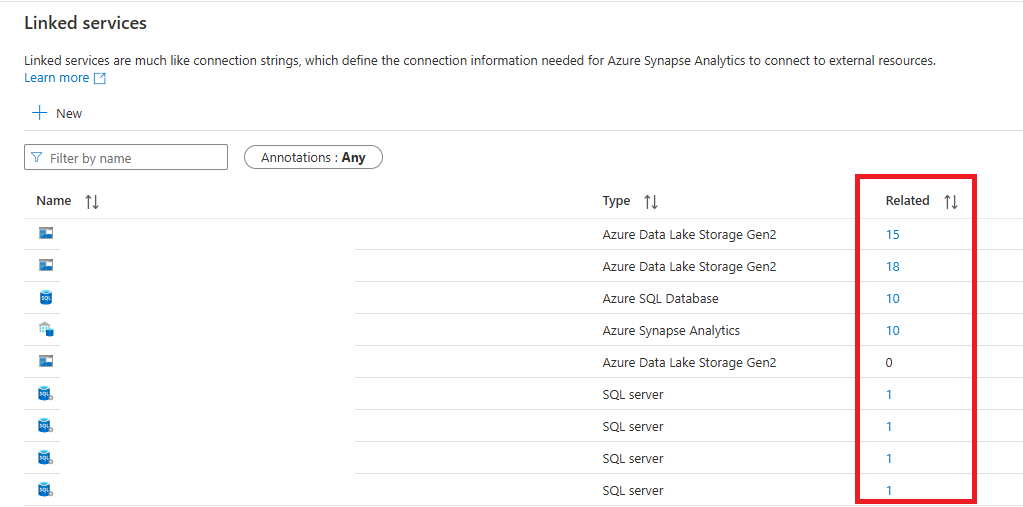
    Once you are on the Linked Services tab, there is a column in the list of services called “Related” which lists the number of related data sources for each Linked Service. If you click on the number, it will open a new pane of information telling you which data sources are created using that Linked Service.

    Screenshot showing the Linked Services page in the Synapse Analytics studio management tab, where you can view the data sources related to a Linked Service.
    Click on the linked numbers in the Related column of the Linked Services list to see data sources using the Linked service
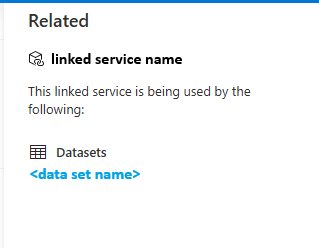
    Screenshot showing the list of data sources related to a Linked Service
    When clicking on the linked numbers in the Related column, you will see this Related pane.

    In that “Related” pane, the names of any related data sources will be links, so you can click on those to take you to the data source editor for that specific data source within the workspace.

    Seeing which pipelines use a Data Source

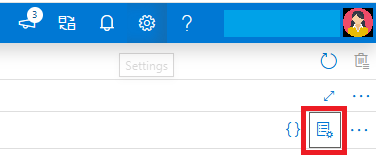
    Once you navigate to the Data Source editor, you are then able to view which pipelines are using that data source. To view that information, you simply need to click on the “Properties” icon in the top right corner of the Data Source editor tab.

    Screenshot showing where to locate the Properties panel of a data source so you can view the related pipelines
    The Properties pane for the Data Source can be accessed from the top right corner of the Studio window.

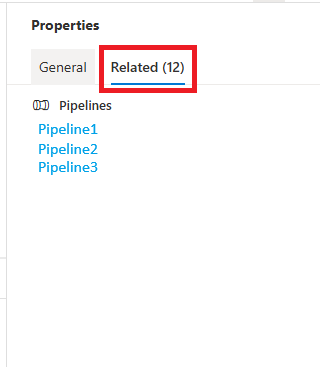
    Once you have the Properties pane opened, click the “Related” tab to view the list of any pipelines that are using the data source.

    Screenshot showing the list of pipelines related to the current Data Source
    In the Properties pane for the Data Source, all related pipelines can be found on the Related tab

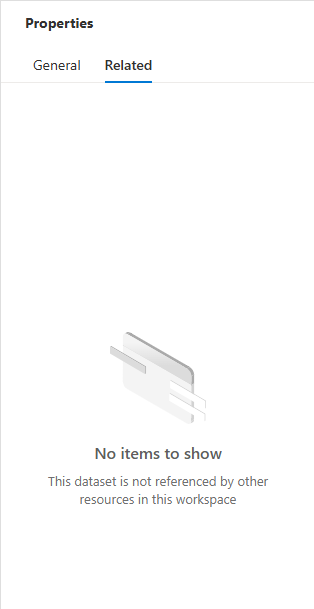
    If there are no pipelines using the data source, you will instead see this on the “Related” tab.

    Screenshot showing an empty Related Pipelines panel for a given Data Source in Synapse Analytics studio
    If there are no pipelines using the Data Source, you will see “No items to show”

    Summary

    I wish I had looked for this information sooner, because I think it could have saved me some time while working with Synapse pipelines. Viewing the Data Sources related to a Linked Service and then what pipelines are using a given Data Source is simple to accomplish and helpful for seeing the relationships between items in your Synapse workspace.

    Related Posts